Tutorial 28: Provider Configuration
Tutorial 28: Provider Configuration — easy-to-understand guide based on official docs
Tutorial 28: Provider Configuration
Welcome back, agent builders! Today we’re diving into one of the most practical parts of running Hermes: configuring your models. If you’ve ever wondered how to pick the right “brain” for your agent, or why there are so many settings for models, this tutorial is for you.
Let’s break it down in plain English.
Two Kinds of Model Slots
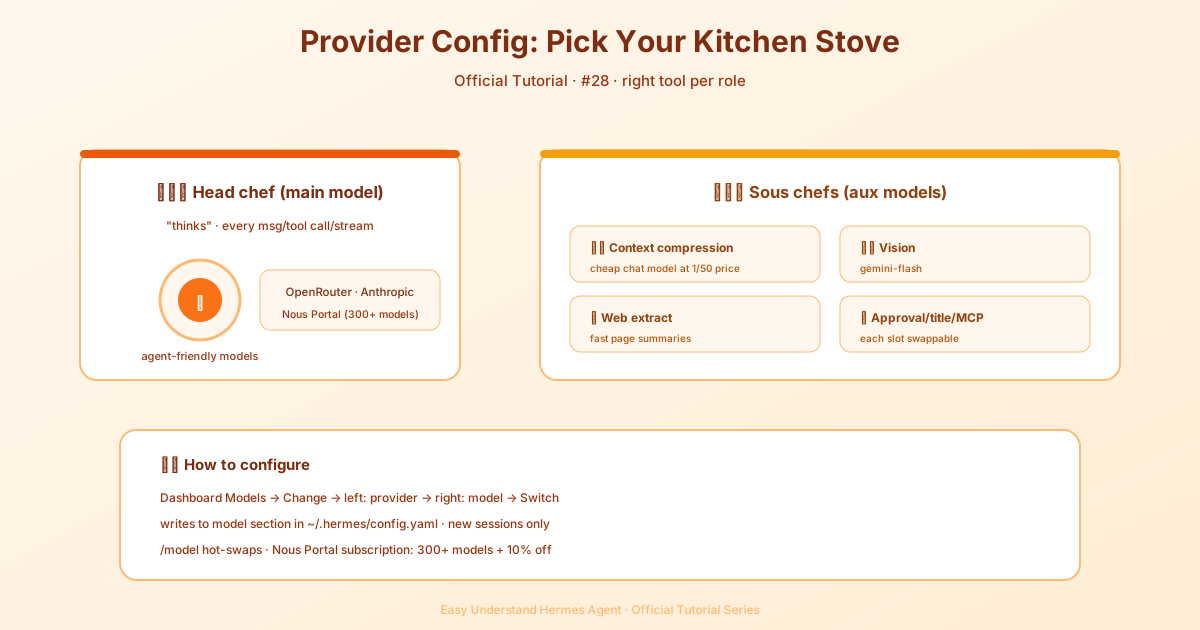
Hermes uses two types of model slots:
- Main model — This is the “thinker.” Every user message, every tool call, and every streamed response goes through this model. It’s the core of your agent’s intelligence.
- Auxiliary models — These are the “helpers.” They handle smaller side-jobs like context compression, vision (image analysis), web-page summarization, approval scoring, MCP tool routing, session-title generation, and skill search. Each has its own slot and can be overridden independently.
Think of it like a team: the main model is the project lead, and the auxiliary models are specialists you bring in for specific tasks.
If you’d rather run models on your own machine instead of a cloud provider, see Local Models.
The Fastest Path: Nous Portal
Before we get into the nitty-gritty, here’s a time-saver. Nous Portal gives you access to 300+ models under one subscription. On a fresh install, just run:
hermes setup --portalThis logs you in and sets Nous as your provider in one command. You can inspect what’s wired up with hermes portal info. Plus, Portal subscribers get 10% off token-billed providers. Not bad!
The Models Page
Open your dashboard and click Models in the sidebar. You’ll see two sections:
- Model Settings — the top panel where you assign models to slots.
- Usage analytics — ranked cards showing every model that ran a session, with token counts, cost, and capability badges.
The top card is the Model Settings panel. The main row shows what the agent will spin up for new sessions. Click Change to open the picker.
Setting the Main Model
When you click Change on the Main model row, a picker dialog opens with two columns:
- Left — authenticated providers. Only providers you’ve set up (API key set, OAuth’d, or defined as a custom endpoint) show up here. If a provider is missing, head to Keys and add its credential.
- Right — the curated model list for the selected provider. These are the agentic models Hermes recommends, not the raw
/modelsdump (which on OpenRouter includes 400+ models including TTS, image generators, and rerankers).
Type in the filter box to narrow by provider name, slug, or model ID. Pick a model, hit Switch, and Hermes writes it to ~/.hermes/config.yaml under the model section.
Important: This applies to new sessions only. Any chat tab you already have open keeps running whatever model it started with. To hot-swap the current chat, use the /model slash command inside it.
Subscription Speed and Extended Context
Speed is a separate setting from reasoning effort. On supported subscription models, Fast requests Priority, and Ultrafast requests the Ultrafast tier. Picking one clears the other, and your choice is remembered per model and carried into a new chat. The profile default lives under Settings → Model → Main model → Speed (agent.service_tier: normal, fast, or ultrafast); Ultrafast only appears for models that offer it, and on a subscription only when your account’s Codex catalog lists it for that model. You can clear a legacy setting with Use standard speed. Note that an accepted request does not guarantee OpenAI actually served the tier you asked for.
Hermes also creates the GPT-6.1 Sol-900k choice from an eligible discovered GPT-6.1 Sol model. The -900k suffix is a local context choice and is removed from the model ID sent to OpenAI. Hermes limits its budget to the account catalog’s maximum, and Codex may report a smaller usable context after its own reserve. If a new model is missing, use Refresh models. A failed discovery uses short-lived compatibility hints instead of caching them as a successful account catalog.
Mid-Session Switches and Context Warnings
When you switch models inside an active session, Hermes estimates whether your next message will run preflight context compression against the new model’s window. If the session is already near or above that model’s compression threshold, the switch reply includes a warning. The switch still applies immediately; compression runs on the first user message after the switch.
Heads up: Mid-session switches reset the prompt cache. Prompt caches are keyed to the model serving the request, so any mid-conversation model change — an explicit /model switch, an automatic fallback, or a credential-pool rotation onto a different account — means the next message re-reads the entire conversation at full input-token price instead of the cached (~75–90% discounted) rate. On a long session, this one-time re-read can dwarf the per-token difference between the two models. Switch when you need to, but prefer doing it early in a conversation or right after starting a fresh session.
An explicit /model switch also rewrites the Model: (and Provider:) line inside the system prompt so the agent knows what it is running on. That is a deliberate, one-time change: the first request after the switch misses the cached prefix once, and everything after the system prompt stays byte-identical. Automatic fallbacks rewrite the same line only in memory — the stored session keeps the primary’s labels, so a restored primary replays a byte-identical prompt.
Because of that one-time re-read cost, Hermes asks for explicit confirmation before applying a mid-session switch when the live session already holds a large context (default: 100,000 tokens, measured from the latest provider-billed prompt size). You can tune or disable this in config.yaml:
model:
  # Ask before mid-session switches when the session exceeds this many
  # context tokens (the next reply re-reads them uncached). 0 disables.
  switch_context_confirm_tokens: 100000
Re-selecting the model you’re already on never prompts (the cache stays warm), and sessions with no measured context (fresh sessions, non-live surfaces) are exempt.
Unattended Data-Training Tiers
Models with a -contributor suffix (e.g. muse-spark-1.2-contributor, muse-spark-1.3-contributor) are discounted because the vendor may train on your prompts and completions. Interactive model selection always shows a confirmation prompt. But non-interactive startup paths like Kanban workers and cron agents fail closed because they can’t ask that question.
If training on the unattended workload’s data is acceptable, record a persistent acknowledgement:
hermes config set security.allow_data_training_tiers_noninteractive trueHermes still prints the full data-policy warning and the acknowledgement key on every unattended startup, so worker logs retain an audit trail. This setting does not approve expensive-model or provider-routing warnings, and it does not replace the interactive confirmation prompt. Revoke it with:
hermes config unset security.allow_data_training_tiers_noninteractiveSetting Auxiliary Models
Click Show auxiliary to reveal the 11 task slots. Every auxiliary task defaults to auto — meaning Hermes tries your main model for that job too. If that route is unavailable or hits a capacity-style failure, auto follows any task-specific fallback chain, then the main fallback chain. It never guesses a provider you did not configure: with a main provider selected and no fallback declared, the side task is skipped with a warning rather than billed to another account you happen to be logged into. (Hermes’ built-in discovery chain only runs when no main provider is selected at all.)
Override a specific task when you want a cheaper or faster model for a side-job. For example, you might want a small, fast model for session-title generation but keep your powerful main model for thinking.
One More Note on the model: Schema
On a brand-new install, the bundled default config has model: "" (an empty string sentinel meaning “not configured yet”). The first time you run hermes setup or hermes model, that key is upgraded in-place to a mapping with provider, default, base_url, and api_mode sub-keys. If you ever see an empty string in config.yaml, just run hermes model (or click Change in the dashboard) and Hermes will write the dict form for you.
Per-Provider Request Options
Provider entries in your providers: config accept a few extra knobs that shape how Hermes talks to the endpoint.
extra_headers — a mapping of extra HTTP headers attached to every LLM request routed to that provider’s base URL. Handy for Cloudflare Access service tokens, proxy auth, or custom bearer schemes. Header values routinely carry credentials, so Hermes never logs them. It applies to OpenAI-compatible routes and to anthropic_messages routes (the main client, /model switches, rebuilds, and auxiliary clients alike); bedrock_converse does not use it. A relay behind a WAF that rejects the SDK’s default User-Agent is the typical reason to set one — Hermes reports such a 403 as a firewall/CDN block rather than an API-key rejection.
session_affinity_header — the NAME of a header that carries Hermes’ conversation id on every request to that provider (main turn plus auxiliary calls such as compression and titles). Off unless set — Hermes never sends a session identifier to an endpoint that did not ask for one. Session-aware proxies fronting a stateful backend (like LiteLLM’s x-litellm-session-id) otherwise have nothing to correlate an agent loop on and treat nearly every request as a new conversation. The value is opaque, stable across the turns of one conversation (including compaction), and different for every conversation.
discover_models — set to false (default true) to skip querying the endpoint’s /models listing and use only the models you configured on the entry. Handy for gateways whose model listing is slow, unreliable, or noisy.
Answers That Arrive in the reasoning Field
Some OpenAI-compatible servers return the whole answer in the reasoning field with empty content. Hermes does not show reasoning as the reply by default, because most providers put private chain-of-thought there. It retries instead. If your server’s parser really does put the final answer in reasoning, opt that model in with answer_in_reasoning:
providers:
  local-vllm:
    api: http://127.0.0.1:8000/v1
    models:
      my-reasoner:
        answer_in_reasoning: true
To opt in every model on a provider, put the flag in a provider-level capabilities: block (capabilities: {answer_in_reasoning: true}). Hermes re-reads the opt-in on the active route on every turn, in the CLI, TUI and gateway alike, so it survives a /model switch to another model on the same provider. A fallback or any other provider does not inherit it, and OpenRouter routes are never trusted, even with the flag set.
📖 Official Docs
This article is based on the official Hermes Agent documentation:Official docs › user-guide/configuring-models