Tutorial 13: How to Choose the Right AI Model in Hermes
Pick the best model for your Hermes Agent — provider options and speed vs quality trade-offs, explained for beginners.
Tutorial 13: How to Choose the Right AI Model in Hermes
Welcome back to the Hermes Agent series! Today we’re tackling a question every user asks sooner or later: which AI model should I actually use? With hundreds of options out there, it’s easy to feel overwhelmed. But here’s the good news — Hermes is built to make this decision way simpler than you’d think.
Two Kinds of Model Slots
First, let’s clear up a common point of confusion. Hermes doesn’t just use one model — it uses two categories:
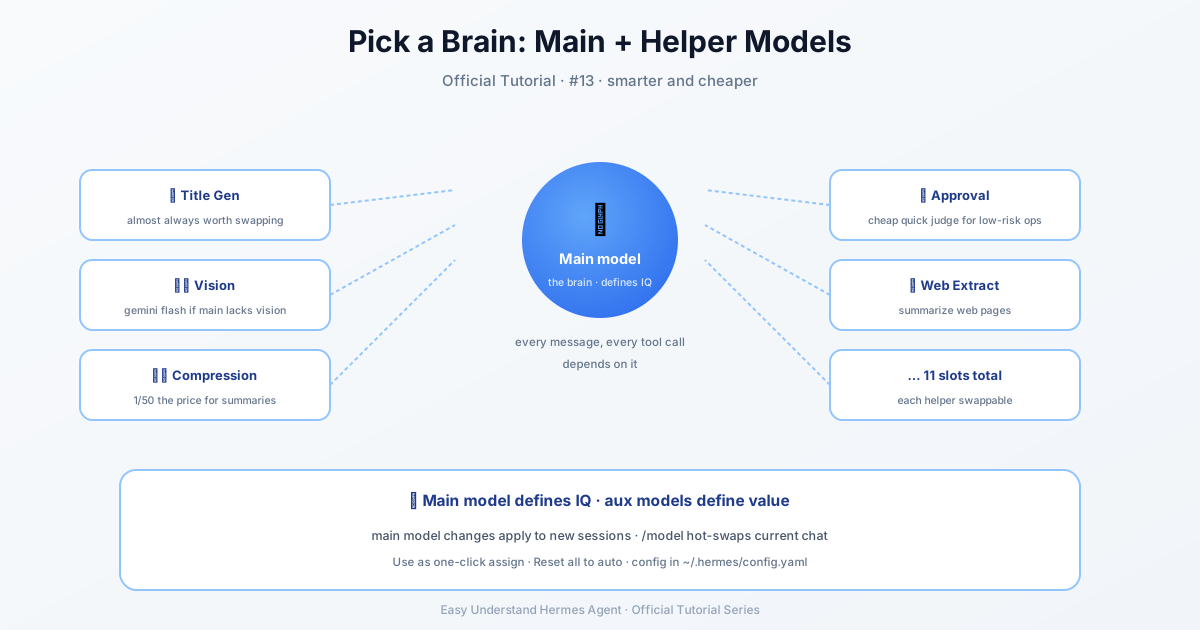
- Main model — this is the “brain” of your agent. Every user message, every tool call, every streamed response goes through it. Think of it as the star of the show.
- Auxiliary models — these are the behind-the-scenes helpers. Hermes uses them for smaller jobs like context compression, image analysis, web-page summarization, approval scoring, MCP tool routing, session-title generation, and skill search. Each of these 11 tasks has its own slot, and you can override them independently.
The Fastest Path: Nous Portal
If you’re just getting started, here’s a pro tip: Nous Portal gives you access to 300+ models under a single subscription. On a fresh install, just run:
hermes setup --portalThat single command logs you in and sets Nous as your provider. You can inspect what’s wired up with hermes portal info. Bonus: Portal subscribers get 10% off token-billed providers. Not bad, right?
The Models Page
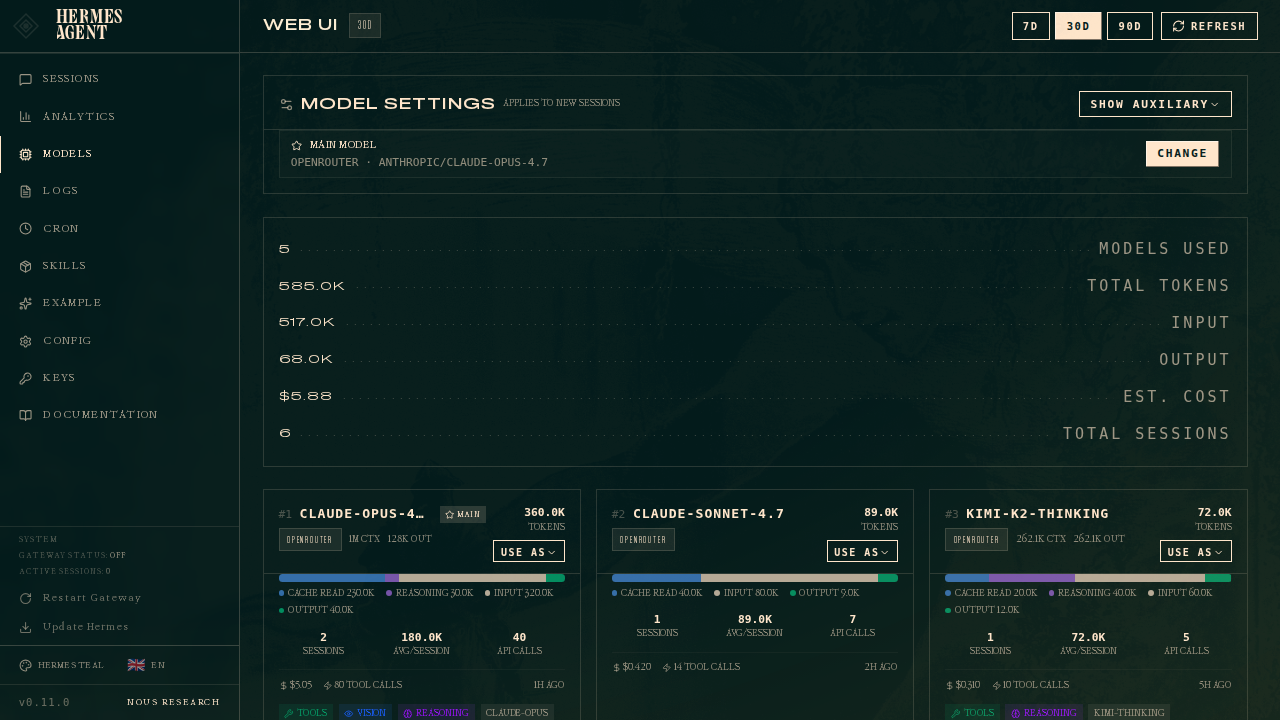
Open your dashboard and click Models in the sidebar. You’ll see two sections:
- Model Settings — the top panel where you assign models to slots.
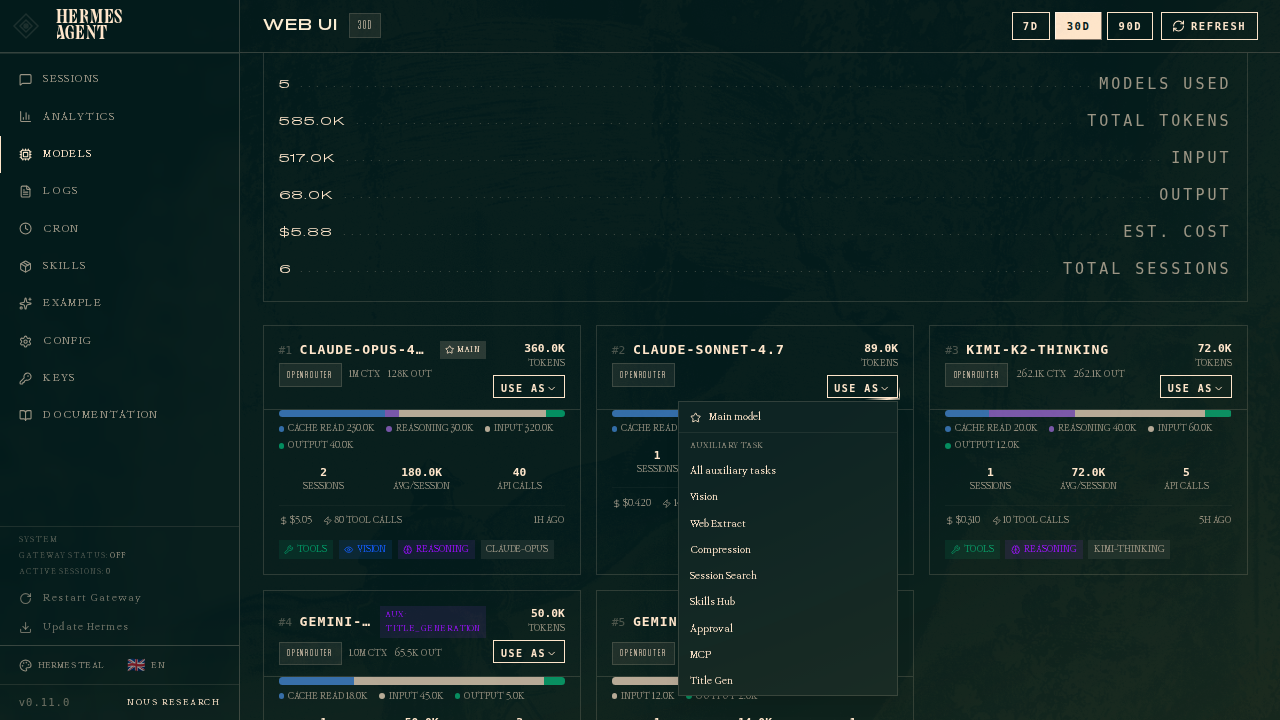
- Usage analytics — ranked cards showing every model that ran a session, with token counts, cost, and capability badges.
The main row shows what your agent will use for new sessions. Click Change to open the picker.
Setting the Main Model
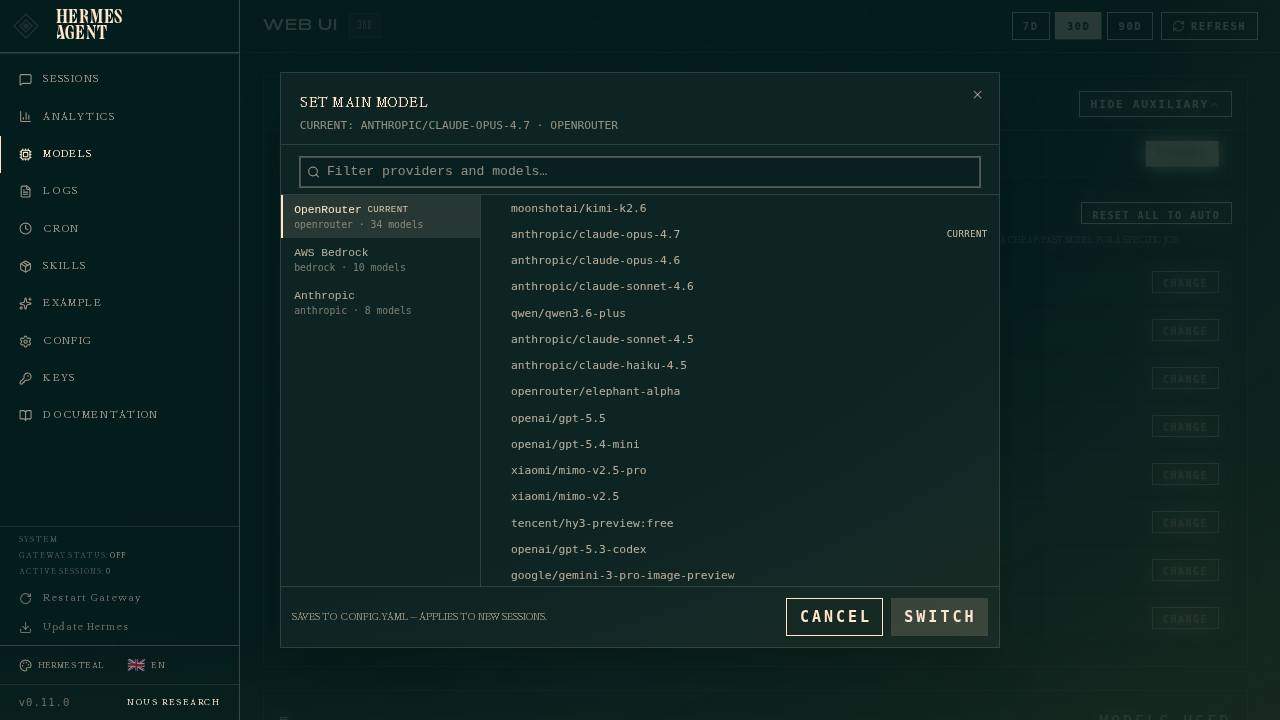
The picker dialog has two columns:
- Left — your authenticated providers. Only providers you’ve actually set up (API key, OAuth, or custom endpoint) show up here. Missing one? Head to Keys and add the credential.
- Right — the curated model list for that provider. These are the agentic models Hermes recommends — not the raw
/modelsdump (which on OpenRouter includes 400+ models, including TTS and image generators you don’t need).
Type in the filter box to narrow things down. Pick a model, hit Switch, and Hermes writes it to your config file.
Important: This applies to new sessions only. If you have a chat tab already open, it keeps running whatever model it started with. To hot-swap the current chat, use the /model slash command inside it.
A Word About Switching Mid-Session
Switching models mid-conversation works, but there’s a catch: prompt caches reset. Since caches are keyed to the model serving the request, any mid-conversation change means the next message re-reads the entire conversation at full input-token price instead of the cached (~75–90% discounted) rate. On a long session, that one-time re-read can cost more than the per-token difference between models. So switch when you need to, but prefer doing it early in a conversation.
Because of that one-time re-read cost, Hermes asks for explicit confirmation before applying a mid-session switch when the live session already holds a large context (default: 100,000 tokens, measured from the latest provider-billed prompt size). You’ll see this prompt in the CLI and TUI /model command and picker, and for a typed gateway /model in a chat with an active agent. Tune or disable it in config.yaml:
model:
  # Ask before mid-session switches when the session exceeds this many
  # context tokens (the next reply re-reads them uncached). 0 disables.
  switch_context_confirm_tokens: 100000
Re-selecting the model you’re already on never prompts (the cache stays warm), and sessions with no measured context (fresh sessions, non-live surfaces) are exempt.
Unattended Data-Training Tiers
Some models with a -contributor suffix (like muse-spark-1.2-contributor or muse-spark-1.3-contributor) are discounted because the vendor may train on your data. Interactive selection always shows a confirmation prompt. But for unattended workloads (Kanban workers, cron agents), Hermes fails closed because it can’t ask you.
If you’re okay with this for unattended tasks, record a persistent acknowledgement:
hermes config set security.allow_data_training_tiers_noninteractive trueHermes still prints the full data-policy warning on every startup, so you keep an audit trail. Revoke it anytime with hermes config unset security.allow_data_training_tiers_noninteractive.
Setting Auxiliary Models
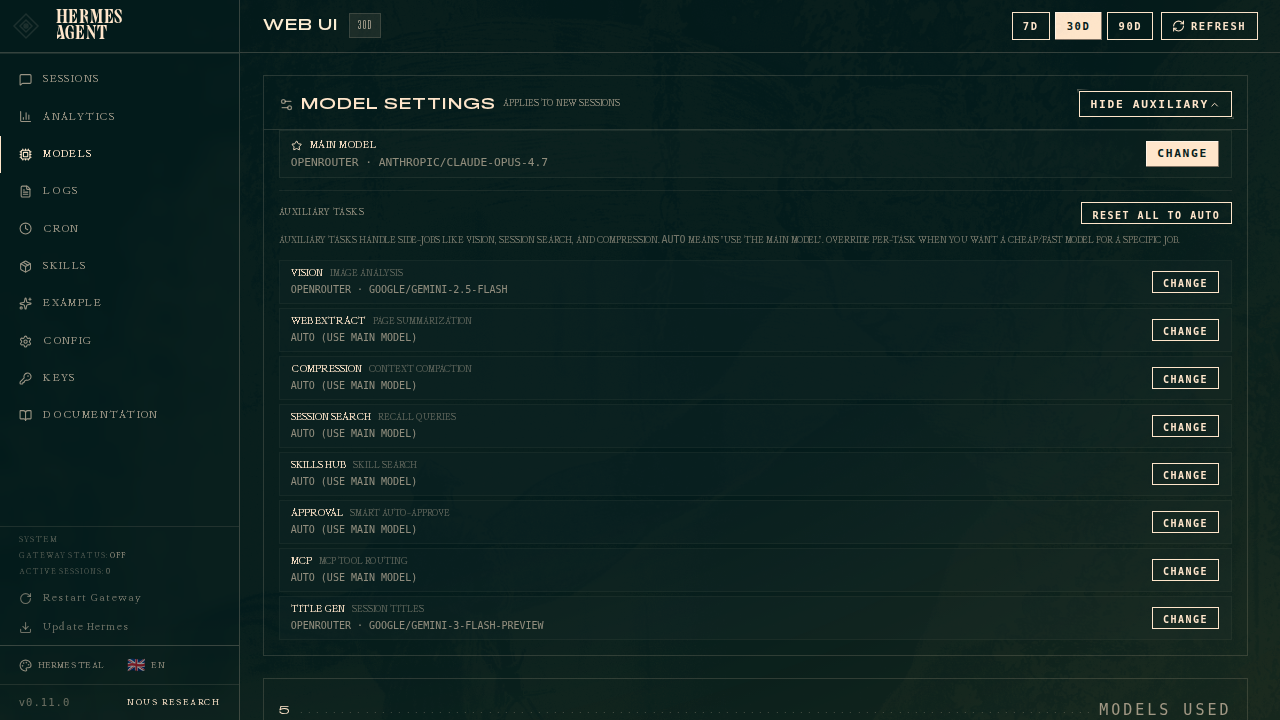
Click Show auxiliary to reveal the 11 task slots. Every auxiliary task defaults to auto — meaning Hermes tries your main model for that job too. If that route is unavailable or hits a capacity-style failure, it follows any task-specific auxiliary.<task>.fallback_chain, then the main fallback_providers / fallback_model chain. It never guesses a provider you did not configure: with a main provider selected and no fallback declared, the side task is skipped with a warning rather than billed to another account you happen to be logged into. (Hermes’ built-in discovery chain only runs when no main provider is selected at all.)
Override a specific task when you want a cheaper or faster model for a side-job. For example, you might want a tiny model for session-title generation but keep your big model for vision tasks.
The Bottom Line
Choosing the right model doesn’t have to be stressful. Start with the main model that fits your budget and task complexity, let the auxiliary slots default to auto, and only override when you notice a bottleneck. Hermes handles the rest.
Happy modeling! 🚀
Official interface screenshots
📖 Official Docs
This article is based on the official Hermes Agent documentation:Official docs › user-guide/configuring-models